
Anil Arora is the former Chief Statistician of Canada, adjunct lecturer at the Harvard Kennedy School and a CIGI board member.
Artificial intelligence has moved from a promising general-purpose technology to an increasingly consequential layer of economic, social and public infrastructure. It is already raising productivity, expanding access to expertise, accelerating scientific discovery and creating new ways to deliver services. At the same time, AI systems are implicated in fraud, manipulation and cyberattacks and unreliable results and misinformation. The most capable systems are demonstrating early autonomous behaviour that could eventually make meaningful human intervention more difficult - and, according to some, impossible.
The 2026 International AI Safety Report captures the dilemma well. Some harms are already documented, while others remain uncertain but could be severe or catastrophic. Capabilities are advancing faster than the evidence needed to assess them, leaving governments with an uncomfortable choice: act too early and risk locking in ineffective controls, or wait for certainty and discover that the most consequential risks have already escaped our ability to manage them. The report also notes that 12 companies published or updated frontier safety frameworks in 2025, an important development, but most remain voluntary.1
The pace of change is not theoretical. The United Kingdom AI Security Institute reports that the length of cyber tasks that frontier models can complete has been doubling roughly every eight months. In controlled self-replication evaluations, success rates increased from below 5 per cent in 2023 to more than 60 per cent by 2025, although the Institute emphasizes that present systems remain unlikely to reproduce successfully in real-world conditions.2 These findings should not be sensationalized. They should, however, change the standard of evidence required before highly capable systems are connected to critical infrastructure, financial authority, sensitive research environments or the ability to act independently.
Recent positions from AI companies point in the same direction. Anthropic’s Responsible Scaling Policy links stronger safeguards to defined capability thresholds and permits pausing development when controls are inadequate.3 OpenAI has called for mandatory, capability-based national requirements and international standards governing when development should slow or stop.4 The significance is not that companies should regulate themselves. It is that even those building the technology increasingly acknowledge that voluntary commitments and conventional software regulation are not enough.
Governance must begin with purpose and institutional capacity…
My experience working with national and international organizations has reinforced a simple lesson: legal authority is necessary, but it is rarely sufficient. Institution trust and effectiveness depend on professional competence, transparent methods, credible evidence, ethical leadership and the confidence of the people they serve. A program can be technically lawful and still lose public support if people do not understand why data are being used, who benefits, what protections exist or who will be accountable when something goes wrong.
This is the difference between compliance and social licence. Compliance establishes the minimum expectations for an institution. Social licence reflects whether people believe its actions are legitimate, proportionate and aligned with the public interest. AI raises this distinction sharply because its effects are not confined to a single offering. Models are trained on data drawn from society, incorporated into decisions across institutions and capable of influencing how people receive information, services, employment, credit, education and health care.
The appropriate objective is governed acceleration. Innovation should remain open where risks are limited and reversible; stronger obligations should apply as consequences, autonomy and data sensitivity increase; and development or deployment should be paused when capabilities exceed the controls available to manage them. This approach is consistent with the risk-based direction of the European Union AI Act, the Council of Europe Framework Convention and the OECD’s emphasis on combining enablers, guardrails, engagement and measurable impact.567
An integrated set of governance mechanisms are critical - here’s seven principles:
Every AI initiative should begin with articulation of the public or organizational purpose it is intended to serve. Leaders should be able to explain the problem, the affected population, the expected benefit, the alternatives considered and how success will be measured. Technology should not become its own rationale.
Obligations should be graduated according to capability, consequence, autonomy, deployment context, data sensitivity and reversibility. Low-risk tools should face proportionate requirements. Applications that affect rights, benefits, health, safety or livelihoods should require impact assessment, meaningful human accountability and avenues for explanation and appeal. Frontier systems that materially increase cyber, biological, chemical, autonomous or self-improvement risks should face licensing and pre-deployment authorization. Some uses - including autonomous decisions over nuclear weapons or other irreversible uses of force - should remain clear societal red lines.
AI governance cannot be separated from data governance. Organizations need to know what data they possess, the authority under which it was collected, its quality and representativeness, how it moves across systems, who can access it and how long it should be retained. Privacy, security, intellectual property, Indigenous and sovereign data interests, cross-border flows and the provenance of synthetic or AI-generated content must be addressed as parts of one lifecycle.
This requires investment in metadata, standards, interoperability, secure platforms, identity and access controls, audit logs and the people capable of operating them. Weak data foundations do not merely reduce model performance. They can scale bias, error and privacy risk. Conversely, trusted and well-governed data infrastructure allows organizations to innovate more quickly because responsibilities and permissible uses are clear. NIST’s AI Risk Management Framework provides a useful operational foundation, but it must be connected to enterprise data, cybersecurity, procurement and records-management systems.8
For consequential and frontier systems, a developer or deployer should be required to present a safety case: a structured, evidence-supported argument that a system is acceptably safe for a defined operating context. The evidence should include threat modelling, capability evaluations, adversarial testing, privacy and security assessment, examination of foreseeable misuse, residual-risk analysis and the safeguards required for deployment.
Independent evaluators and public authorities need secure access to the systems and evidence necessary to challenge those claims. Assurance cannot end at release. Models, data, tools and deployment environments change, and systems may perform differently in testing than in practice. Continuous monitoring, periodic reassessment and new authorization following material changes should therefore become standard. Transparency must be calibrated: regulators need access to sensitive information, while public reporting must avoid disclosing details that create new security risks.
A so-called “kill switch” should not be treated as a single button or a rhetorical promise. Effective containment is a layered operational capability: restricting tools and network access, revoking credentials, throttling use, isolating systems, stopping training, suspending deployment, rolling back models, preserving forensic evidence and maintaining continuity for essential services. These controls must be designed and tested before deployment, not invented during or after a crisis.
Emergency authority also needs governance. The conditions for intervention, the responsible decision-makers, the evidence threshold and the duration of a suspension should be defined in advance. For the most consequential systems, I would require dual authorization (two-key system), independent review and an auditable record. Otherwise, the control intended to protect society can itself become a cybersecurity vulnerability, a source of commercial manipulation or an instrument of political abuse.
Responsibility must follow the capacity to prevent harm. Boards should approve risk tolerances for material AI uses, designate accountable executives and receive reporting on capabilities, incidents, unresolved risks and realized value. Developers, application builders, deployers and users have different responsibilities; law should allocate obligations according to the information and control each possesses rather than allowing accountability to be diffused or disappear across a complex supply chain.
Mandatory reporting should cover serious incidents, dangerous unexpected behaviour, model-weight theft, safeguard failures and significant misuse. Protected near-miss reporting and strong whistleblower safeguards would allow the field to learn as aviation, health regulation and other high-reliability sectors have learned. Good-faith disclosure should be encouraged, while concealment, retaliation and knowingly false safety claims should result in meaningful consequences. Liability and financial assurance should be strongest where risks are catastrophic, without imposing the same burden on small firms and low-risk applications.
Trust cannot be created through communications after the important decisions have already been made. People affected by consequential systems should know when AI is being used, what role it plays, what information informs/enables the decision, who remains accountable and how an outcome can be challenged. Independent experts, employees, civil society and affected communities should participate early enough to change the design rather than merely react to it.
Social licence is also connected to distribution. Leaders should assess who receives the benefits, who bears the risk, whether services remain accessible to those with lower digital or AI literacy, and whether AI concentrates economic and informational power. The measure of success cannot be adoption alone and extend to impact. It must include service quality, productivity, rights, inclusion, trust, safety, environmental cost and the durability of public value.
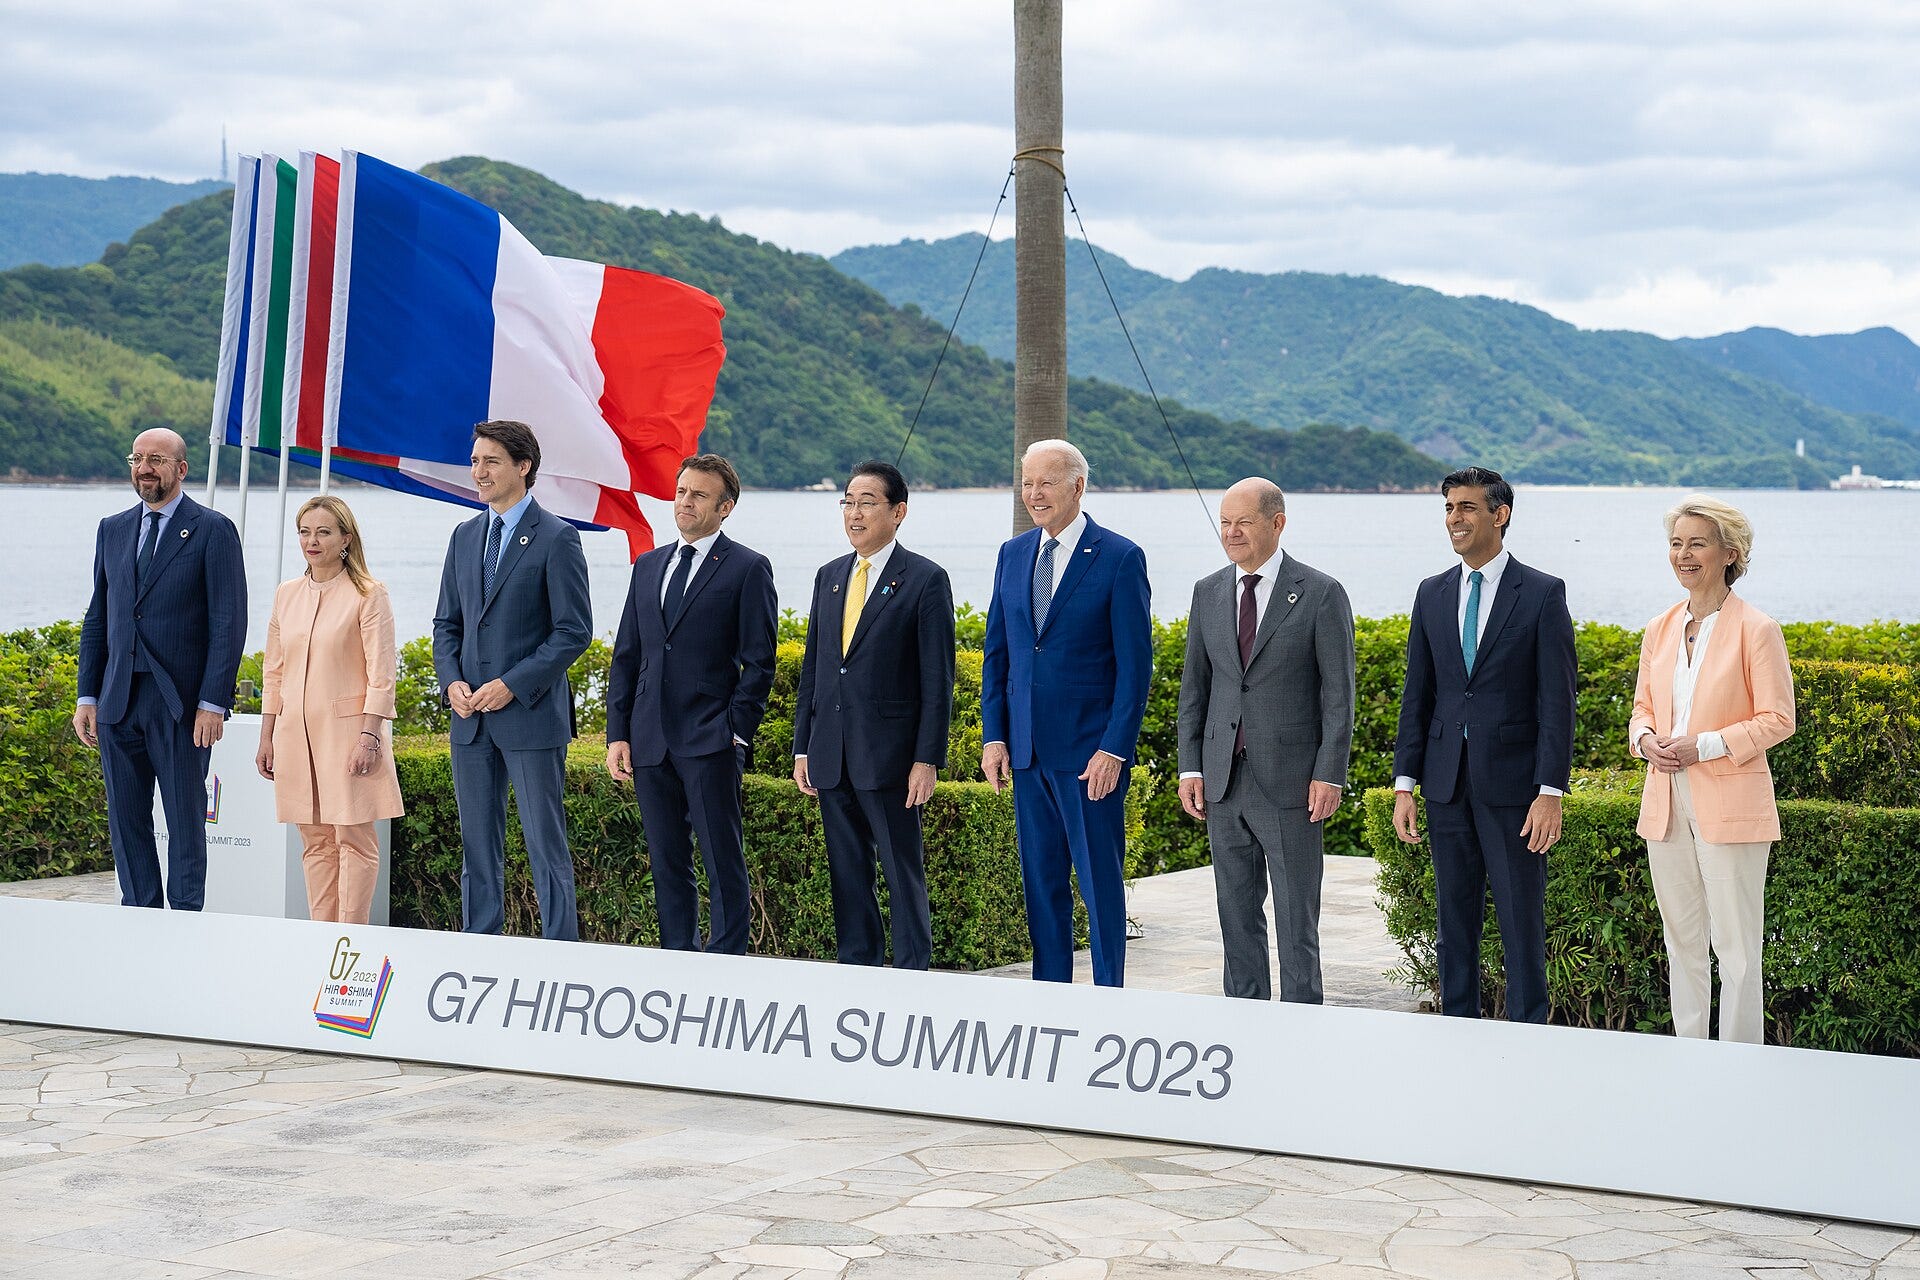
AI systems, model weights, data and compute cross borders, while legal authority remains largely national. A patchwork of incompatible rules increases compliance costs without necessarily increasing safety. International alignment should therefore focus on shared capability definitions, interoperable evaluation methods, incident taxonomies, model and compute security, reciprocal assurance and crisis communication. The United Nations, OECD, Council of Europe, G7 Hiroshima Process and ITU each provide elements of this emerging architecture.910
The nuclear analogy is helpful in reminding us that strategic competitors may need to exercise mutual restraint even when trust is limited. Clearly, AI is more diffuse, more commercially embedded and harder to “count” than a volume of nuclear material. Deterrence without verification will be inadequate. Any international regime must combine common thresholds with evidence, technical monitoring and reciprocal scrutiny, while ensuring that developing countries participate in setting the rules and have the capacity to implement them.
Finally, governance must be able to learn and adjust. Legislatures should set rights, duties, prohibitions and institutional mandates. Technically capable regulators should update evaluation protocols and standards as evidence develops, subject to transparency and oversight. Regulatory sandboxes, public-interest research capacity, shared testing infrastructure and clear procurement rules can lower barriers to responsible innovation. Adaptive governance should mean disciplined learning within democratic boundaries, not permanent discretion for governments or firms.
The leadership test…
Together, these seven points place AI governance where it belongs - inside the leadership and operating system of an institution, not beside it as a compliance exercise. The central governance failure would be to treat this moment and challenge as a technical problem simply delegated to specialists. The decisions are ultimately about purpose, acceptable risk, institutional legitimacy and the distribution of power and benefit. Senior leaders must understand enough to ask the right questions, insist on evidence, make trade-offs visible and halt initiatives whose risks cannot be responsibly managed.
This framework maps out a way forward that is neither an unrestricted race nor an indefinite pause. It is a system in which innovation is encouraged below critical thresholds, evidence of safety is required before consequential deployment, development pauses when safeguards fall behind capabilities, and certain uses remain beyond the boundary society is or should be prepared to accept. Our ability to benefit from AI will ultimately depend not only on what the technology can do, but on whether our institutions can remain capable, accountable and worthy of trust while governing it.
If you enjoyed this, you may also like from Sage:


The governed-acceleration framing lands because it moves the ethical question upstream: pausing when capabilities outrun controls is a decision made by whoever holds the build, not by whoever uses it later. That is the part most governance writing skips — once a channel is built, the choices that matter have mostly already been made, and the remaining ethics is about how much choice is left and who is holding it. Your social-licence point sharpens this: a licence is granted to the party that controls the gates, so naming that party at design time is the whole game. I wrote about this as the Oppau plant problem — the same ammonia channel that fed a nation was reorganized for a different customer thirteen months after first firing: https://seldondance.substack.com/p/after-the-build
Thank you. The framework is strong on governance architecture, but what is still missing is a more explicit accountability mechanism that translates principles into decisions made throughout the system lifecycle. In particular, engineers need clearly defined duties to identify hazards, document assumptions and limitations, challenge unsafe requirements, maintain traceability from design decisions to deployment outcomes, and escalate concerns when organizational incentives conflict with safety. A safety case should therefore not be only a management or regulatory artifact; it should be supported by engineering evidence, named technical owners, acceptance criteria, change-control procedures and explicit stop-work authority. The framework would also benefit from distinguishing responsibility, accountability and liability more precisely: responsibility can be distributed across teams and suppliers, but accountability for a decision should remain identifiable. Without these mechanisms, boards and regulators may have formal oversight while the people with the most direct knowledge of technical risk lack the authority, protection or institutional pathways needed to act on it.
A second gap is the absence of a sufficiently concrete failure-learning and assurance loop connecting incidents, near misses, operational data and subsequent engineering changes. The proposed monitoring and reassessment requirements should specify how evidence is captured, who reviews it, what constitutes a material change, when authorization must be revisited, and how lessons are incorporated into standards, models, procurement requirements and organizational practice. This is particularly important because AI risks can emerge from interactions among models, data, users and operating environments that were not foreseeable during development. Engineers therefore need an obligation and protected mechanism to report emerging hazards without waiting for demonstrable harm, alongside independent review of disputed risk assessments and periodic validation that controls remain effective in practice. In this sense, the missing principle is not another layer of governance, but institutionalized professional accountability for anticipating, evidencing, communicating and learning from failure—so that AI governance operates as a continuous engineering discipline rather than a set of approvals completed before deployment.